Skip to content

EthenEthenEthen

Pricing
Login↗Platform↗Try Ethen↗

Upcube / Ethen Research Lab

Ethen Research Lab

Researching what comes next.

Ethen Research Lab studies intelligence, computing, science and frontier technology. It publishes methods, protocols and results with an explicit evidence status, and it builds the knowledge and capability that strengthen Ethen and the wider mission.

Ethen Research Lab is Upcube’s research organization and public publication program. Each publication is labelled with its evidence status. Looking for the AI research workspace? That is the Ethen Research product, which is separate from this publication record.

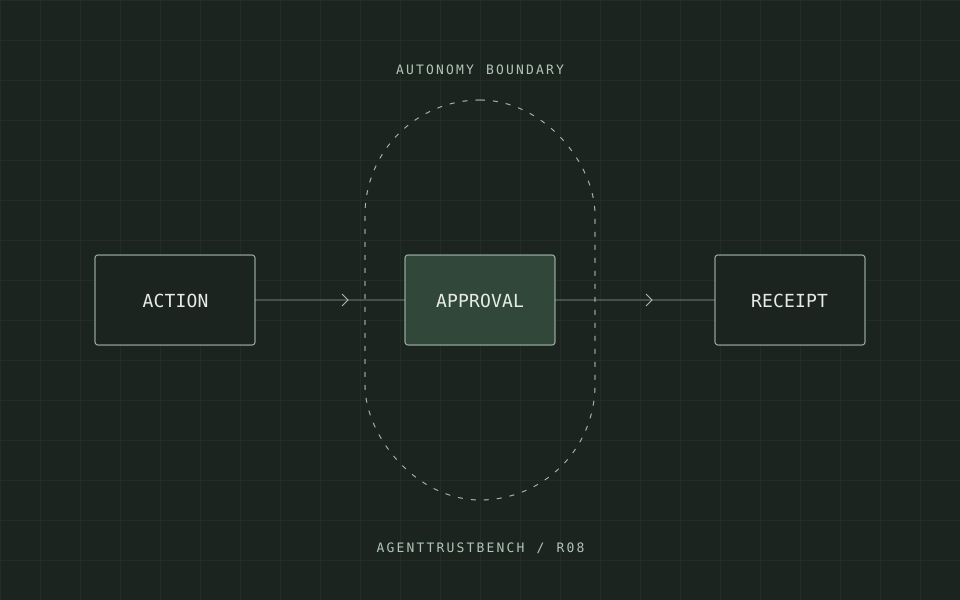
  • R08AgentTrustBench system card: autonomy boundaries on one pinned build. System Evidence
  • P01Verified Adaptive Intelligence: Learning From Work That Can Be Proven. Research Synthesis
  • P02From AI Traces to Verified Experience. Research Synthesis
  • P03Work Receipts: A Verifiable Record for Autonomous AI Work. Proposal / Hypothesis
  • P04Mandates: Compiling Human Intent Into Bounded Agent Authority. Proposal / Hypothesis
  • P05Commitment Graphs: Why AI Agents Need to Know What Is Still Unfinished. Proposal / Hypothesis
  • P06Recovery Atlas: Teaching AI Agents When to Retry, Reconcile, Escalate, or Stop. Proposal / Hypothesis
  • P07Evaluating the Evaluators: Reward Integrity for AI Agents. Research Synthesis
  • P08Faros: Researching How Intelligence Should Choose Intelligence. Research Synthesis
  • P09Why Learned AI Model Routing Must Beat Good Rules. Research Synthesis
  • P10Counterfactual Replay for AI Agents. Proposal / Hypothesis
  • P11Model Change Assurance: Testing AI Upgrades Before They Reach Real Work. Research Synthesis
  • P12What Makes AI Data Defensible?. Research Synthesis
  • P13The Outcome Warehouse: Turning Completed AI Work Into Research Assets. Research Synthesis
  • P14Skill IR: Toward Model-Independent Agent Capabilities. Proposal / Hypothesis
  • P15The Capability Transfer Ledger: Measuring Whether AI Skills Survive Model Upgrades. Proposal / Hypothesis
  • P16Evidence-Preserving Context: Compressing Agent Memory Without Losing Obligations. Proposal / Hypothesis
  • P17Rights as Infrastructure: Building AI Datasets That Know How They May Be Used. Proposal / Hypothesis
  • P18A Rights-Aware Dataset Compiler for AI Training and Evaluation. Proposal / Hypothesis
  • P19Cost Per Verified Outcome: A Better Economic Unit for Agentic AI. Research Synthesis
  • P20Why Better Foundation Models May Make Evaluation More Valuable, Not Less. Research Synthesis
  • P21Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action. Benchmark Design
  • P22VerifiedWork Recovery: Evaluating AI Agents Under Failure and Partial Effects. Benchmark Design
  • P23VerifiedWork Transfer: Measuring Capability Across Model and Tool Changes. Benchmark Design
  • P24VerifiedWork Context: Measuring What AI Agents Must Remember. Benchmark Design
  • P25VerifiedWork Control: Evaluating Delegation, Approval, Revocation, and Agent Authority. Benchmark Design
  • P26How to Test Whether Learned AI Routing Beats Strong Rules. Protocol / Planned Experiment
  • P27How Should We Measure the Reliability of LLM Verifiers?. Protocol / Planned Experiment
  • P28Ethen Synthetic Enterprise: An Executable World for Enterprise-Agent Research. Proposal / Hypothesis
  • P29Unknown Effects in Autonomous AI Systems: Why Timeouts Are Not Permission to Retry. Research Synthesis
  • P30Toward a Failure Genome of Software Agents. Research Synthesis
  • P31Process Memory: Learning How Organizations Actually Get Work Done. Proposal / Hypothesis
  • P32Tenant Replay: Private Evaluation Inside Enterprise Boundaries. Proposal / Hypothesis
  • P33A Research Protocol for Model Change Assurance. Protocol / Planned Experiment
  • P34Why AI Routers Should Log Propensities From Day One. Research Synthesis
  • P35How to Measure Whether AI Skills Survive a Frontier-Model Upgrade. Protocol / Planned Experiment
  • P36How Should We Measure How Much Context an AI Agent Actually Needs?. Protocol / Planned Experiment
  • P37Testing Whether Recovery Knowledge Transfers Across Tools. Protocol / Planned Experiment
  • P38How to Test Whether Verified Experience Improves AI Agents. Protocol / Planned Experiment
  • P39Private AI Improvement Without Raw Data Export. Proposal / Hypothesis
  • P40Toward a Sovereign Improvement Protocol for Enterprise AI. Proposal / Hypothesis
  • System Evidence
  • Research Synthesis
  • Protocol / Planned Experiment
  • Benchmark Design
  • Proposal / Hypothesis

Catalog countCatalog count, drawn from the live publication record.

publications in the record
41
formal research programs ratified
2
system-evidence result, on one pinned build
1
measured results so far
0

Ethen is an AI-native technology organization building toward a research institution. Two formal research programs are ratified; neither has reported a measured result yet.

Research universe

Disciplines compound. They do not live in separate boxes.

Select a field to see how it connects, and how far Ethen's work in it has actually gone.

Artificial & machine intelligenceMathematicsAutonomous scienceRobotics & embodied systemsAutonomous systemsAdvanced computingSemiconductors & hardwareQuantum technologiesPhysicsAstronomy & spaceMaterials scienceNanotechnologyEnergyBiotechnology & computational biologyPharmaceuticals & medicineScientific computing & simulationData & knowledge systems
  • Active Ratified program, running
  • Building Methods or infrastructure under construction
  • Queued Next in line, behind an admission gate
  • Exploring Preparing or partnering; not admitted
  • Long horizon Watched; deferred to a later stage
Active

Artificial & machine intelligence

Agent reliability, verification, routing, evaluation, memory and model behaviour. The Applied program and most of the publication record live here.

Connects to

Research fields

Research programs

Maturity, stated honestly.

A field becomes a program only through an admission gate: a falsifiable question, rights-cleared data, a named independent reviewer and budget headroom. Five simultaneous institutes were rejected on purpose.

Active

Ratified program, running

  • P1 Applied

    Agent Reliability & Verification Science

    When can machine work be trusted, what does one verified outcome cost, and do verifiers fail in measurable ways?

  • P2 Frontier

    Formal Mathematics (Lean 4 / Mathlib)

    Can an agent, the Lean kernel and an independent human formalize known results at a measured, falling cost per verified proof?

Building

Methods or infrastructure under construction

  • M Shared methods

    Memory & gain-measurement methods

    Does structured, verified knowledge improve future work on tasks it has never seen?

Queued

Next in line, behind an admission gate

  • P3 Frontier

    Archive Astronomy

    Anomaly detection and archive mining on public astronomical data.

Exploring

Preparing or partnering; not admitted

  • Applied / Frontier

    Quantum · embodied robotics reliability · materials · computational biology

    Preparing protocols and partners. Not admitted as programs.

Long horizon

Watched; deferred to a later stage

  • Frontier

    Large physics · energy · nanotechnology · pharmaceuticals · wet labs

    Watched and deferred to a later stage of the institution.

No program has produced a measured result yet. When one does, it will appear in the record with its evidence status.

How Ethen researches

A research operating system, with agents as the multiplier.

AI agents scale the work: reading, drafting, running attempts, checking. They are a multiplier, not the point. The institution exists for discovery and for capability that holds up under independent review.

  1. 01

    Question

    A falsifiable question with stated kill criteria.

  2. 02

    Literature & evidence

    What is already known, cited only from verified sources.

  3. 03

    Hypothesis

    A prediction specific enough to be wrong.

  4. 04

    Pre-registration

    Confirmatory protocols are hash-pinned before data collection starts.

  5. 05

    Experiments

    Attempts captured with their rights, cost and verifier outcome.

  6. 06

    Simulation

    Synthetic results are labelled synthetic, never physical evidence.

  7. 07

    Datasets

    Licences checked at capture; failures kept as corpora.

  8. 08

    Evaluation

    Sealed sets, paired designs, stated intervals.

  9. 09

    Verification

    No producer is the sole acceptor of its own result.

  10. 10

    Reproducibility

    Replication by a different operator or pipeline before a claim hardens.

  11. 11

    Provenance & memory

    Claims, evidence and decisions kept in institutional memory with their lineage.

  12. 12

    Publication

    Methods public, corpora sealed; corrections public within 30 days.

  13. 13

    Capability transfer

    Verified findings become verifiers, policies, datasets or methods.

Integrity rules

  • Negative results are recorded, not dropped.
  • Exploratory work is labelled exploratory and cannot become more than provisional.
  • AI systems are never authors. Their role is disclosed in every methods statement.
  • A failed replication marks a claim contested; repeated failure retracts it.

Evidence standards

Uncertainty is part of the design.

Every publication declares how strong its evidence is. Publication type and evidence status are separate: a benchmark design is a specification, not a benchmark result. Select a rung to filter the archive.

  1. Strongest

    Measured / Empirical

    Ethen ran an experiment, benchmark, or measurement and reports the result.

    Publication types on this rung: Evaluation Report, Benchmark Report, Experiment Report

    0publicationsNone yet
  2. System Evidence

    Evidence tied to a specific implemented or pinned Ethen system or build. It does not generalize beyond that build.

    Publication types on this rung: System Card, Evaluation Report, Benchmark Report, Experiment Report

    1publication
  3. Research Synthesis

    Analysis of existing evidence and literature. No new Ethen measurements are implied.

    Publication types on this rung: Survey

    13publications
  4. Protocol / Planned Experiment

    The method is defined. The experiment has not been run, so no results are reported.

    Publication types on this rung: Benchmark Design, Research Protocol

    7publications
  5. Benchmark Design

    A benchmark specification. It has not necessarily been run, and no scores are implied.

    Publication types on this rung: Benchmark Design

    5publications
  6. Weakest

    Proposal / Hypothesis

    A proposed direction, system, or hypothesis that remains untested.

    Publication types on this rung: Research Proposal

    15publications

Research to capability

Knowledge first. Products sometimes.

Not all research is commercialized. Some knowledge, datasets, models and infrastructure stay internal where that is the right call, and some research exists only to find out what is true.

Where a finding can go

  • Publish

    Methods, accepted results and reproduction slices.

  • Keep private

    Sealed evaluation corpora, failure detail, strategic work.

  • Patent

    Where protection serves the mission.

  • License

    Where others can use it better.

  • Spin out

    Where a capability deserves its own organization.

Research questionEvidenceExperimentVerified findingCapabilityDataset · model · systemEthen or another program, when appropriateNew evidenceKnowledge firstproducts sometimes

ConceptualHow a finding can travel. Most stop earlier, and that is by design.

  1. Research question
  2. Evidence
  3. Experiment
  4. Verified finding
  5. Capability
  6. Dataset · model · system
  7. Ethen or another program, when appropriate
  8. New evidence

Research infrastructure

The machinery that makes research compound.

Each system carries its real status. Most are being designed or built; the labels say which.

  • Operating (limited)

    Evaluation systems

    Model-certification, completion-gate and offline-enumeration harnesses exist; the four-arm experiment harness has not run.

  • Designing

    Experiment registry

    Pre-registration with hash-pinned protocols; the machine store is planned.

  • Designing

    Evidence ledger

    One ledger for every attempt, verification, intervention and cost. Not built yet.

  • Designing

    Dataset systems

    A rights-aware dataset compiler that fails closed. Rights at capture is not built.

  • Building

    Knowledge & research memory

    Memory records with provenance, contest and supersession exist in one product; the shared memory is being built.

  • Designing

    Reproducibility

    Pinned inputs and independent re-runs as the rule for every public claim.

  • Future

    Simulation

    Simulated enterprises and robot simulators, each opening at its gate.

  • Future

    Scientific computing & compute

    Rented today; owned compute only past a measured break-even.

  • Building

    Automated research workflows

    Agents already draft, check and run much of the work under human review.

  • Long horizon

    Automated physical experimentation

    No laboratory exists. A long-horizon direction, gated on funded protocols.

Publications

The publication arm of the Lab.

Featured Research

Browse all publications ↓
System Card/AI Security

AgentTrustBench system card: autonomy boundaries on one pinned build

System card for one offline enumeration of a pinned Ethen build: 197 conditions, 194 passed. Not a paper and not a security disclosure.

Evidence status: System Evidence

↳ Offline enumeration · one pinned build
Sep 22, 2026Read research ↗
Diagram of an agent action passing through an approval boundary to a recorded result.
Position Paper/Adaptive Intelligence

Verified Adaptive Intelligence: Learning From Work That Can Be Proven

A research agenda for AI agents that learn only from experience that is verified, rights-cleared and shown to transfer across tasks, tools and model generations.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 15 min readRead research ↗
Cover image for "Verified Adaptive Intelligence: Learning From Work That Can Be Proven". Decorative abstract motif; contains no data.
Research Note/Adaptive Intelligence

From AI Traces to Verified Experience

Logs, traces, trajectories, outcomes and corrections are not the same asset. A research note on what turns agent telemetry into verified experience.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "From AI Traces to Verified Experience". Decorative abstract motif; contains no data.
Benchmark Design/Evaluation & Verification

Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action

A benchmark design for AI agents that take action: executable environments, state-based verification, cost reporting, permissions, recovery and reproducibility.

Evidence status: Benchmark Design

↳ benchmark design; not yet run

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action". Decorative abstract motif; contains no data.
Research Protocol/Adaptive Intelligence

How to Test Whether Verified Experience Improves AI Agents

A research protocol on learning from experience for AI agents: do verified, failure-rich data beat raw traces at matched volume, on held-out work?

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run; no measured gain curves exist

Oct 3, 2026 · 14 min readRead research ↗
Cover image for "How to Test Whether Verified Experience Improves AI Agents". Decorative abstract motif; contains no data.
Research Proposal/Enterprise / Sovereign AI

Toward a Sovereign Improvement Protocol for Enterprise AI

A research proposal for sovereign AI: how enterprise AI could improve across private deployments without raw data leaving the customer boundary.

Evidence status: Proposal / Hypothesis

↳ frontier research proposal; not built; not production-ready; requires privacy, security and legal review

Oct 3, 2026 · 15 min readRead research ↗
Cover image for "Toward a Sovereign Improvement Protocol for Enterprise AI". Decorative abstract motif; contains no data.

All Research

41 publications

The complete published archive.

Position Paper/Adaptive Intelligence

Verified Adaptive Intelligence: Learning From Work That Can Be Proven

A research agenda for AI agents that learn only from experience that is verified, rights-cleared and shown to transfer across tasks, tools and model generations.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 15 min readRead research ↗
Cover image for "Verified Adaptive Intelligence: Learning From Work That Can Be Proven". Decorative abstract motif; contains no data.
Research Note/Adaptive Intelligence

From AI Traces to Verified Experience

Logs, traces, trajectories, outcomes and corrections are not the same asset. A research note on what turns agent telemetry into verified experience.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "From AI Traces to Verified Experience". Decorative abstract motif; contains no data.
Technical Report/Trust & Accountable AI Work

Work Receipts: A Verifiable Record for Autonomous AI Work

A technical report proposing the Work Receipt: one signed record of authority, actions, effects, verification, cost and rights for every unit of autonomous AI work.

Evidence status: Proposal / Hypothesis

↳ architecture proposal; no measured Ethen results

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "Work Receipts: A Verifiable Record for Autonomous AI Work". Decorative abstract motif; contains no data.
Research Note/Trust & Accountable AI Work

Mandates: Compiling Human Intent Into Bounded Agent Authority

A research note on mandates: one object that compiles human intent into AI agent authorization, budgets, approvals, delegation limits, expiry and revocation.

Evidence status: Proposal / Hypothesis

↳ architecture proposal; cites one published measured Ethen system card (AgentTrustBench R08)

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Mandates: Compiling Human Intent Into Bounded Agent Authority". Decorative abstract motif; contains no data.
Research Proposal/Adaptive Intelligence

Commitment Graphs: Why AI Agents Need to Know What Is Still Unfinished

A research proposal for commitment graphs: tracking intent, obligations, preconditions, effects and evidence so AI agents stop declaring unfinished work complete.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "Commitment Graphs: Why AI Agents Need to Know What Is Still Unfinished". Decorative abstract motif; contains no data.
Research Proposal/Adaptive Intelligence

Recovery Atlas: Teaching AI Agents When to Retry, Reconcile, Escalate, or Stop

A research proposal on AI agent error recovery: branch each failure in a sandbox into candidate recoveries and learn when to retry, reconcile, escalate or stop.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Recovery Atlas: Teaching AI Agents When to Retry, Reconcile, Escalate, or Stop". Decorative abstract motif; contains no data.
Methods Paper/Evaluation & Verification

Evaluating the Evaluators: Reward Integrity for AI Agents

A methods paper on reward integrity for AI agents: verifier false accepts and rejects, abstention, grader drift, expert disagreement and reward hacking.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Evaluating the Evaluators: Reward Integrity for AI Agents". Decorative abstract motif; contains no data.
Position Paper/Model Intelligence / Faros

Faros: Researching How Intelligence Should Choose Intelligence

A position paper reframing AI model routing as an execution-configuration decision across model, context, tools, verification, recovery, cost and risk.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Faros: Researching How Intelligence Should Choose Intelligence". Decorative abstract motif; contains no data.
Survey/Model Intelligence / Faros

Why Learned AI Model Routing Must Beat Good Rules

A survey of learned LLM routing: what RouteLLM, RouterBench and LLMRouterBench show, why strong rules are the right baseline, and how to test non-inferiority.

Evidence status: Research Synthesis

↳ literature survey; no Ethen measurements

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Why Learned AI Model Routing Must Beat Good Rules". Decorative abstract motif; contains no data.
Research Proposal/Adaptive Intelligence

Counterfactual Replay for AI Agents

A research proposal for counterfactual evaluation of AI agents: replaying completed tasks under alternative models, tools, context and recovery strategies.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Counterfactual Replay for AI Agents". Decorative abstract motif; contains no data.
Research Note/Model Intelligence / Faros

Model Change Assurance: Testing AI Upgrades Before They Reach Real Work

A research note on model change assurance: replaying an organization's own historical tasks to find regressions before an LLM upgrade reaches real work.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Model Change Assurance: Testing AI Upgrades Before They Reach Real Work". Decorative abstract motif; contains no data.
Position Paper/Data & Learning Systems

What Makes AI Data Defensible?

A position paper on the AI data moat: why volume is not defensibility, and eight axes, from rights to outcome density and transfer, that decide what compounds.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "What Makes AI Data Defensible?". Decorative abstract motif; contains no data.
Research Note/Data & Learning Systems

The Outcome Warehouse: Turning Completed AI Work Into Research Assets

A research note on the Outcome Warehouse: storing verified, versioned AI outcome data with corrections, cost, lineage, rights and delayed business results.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "The Outcome Warehouse: Turning Completed AI Work Into Research Assets". Decorative abstract motif; contains no data.
Research Proposal/Context / Skills / Transfer

Skill IR: Toward Model-Independent Agent Capabilities

A research proposal for Skill IR: AI agent skills as portable, testable capability contracts with permissions, verifiers and compatibility records.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "Skill IR: Toward Model-Independent Agent Capabilities". Decorative abstract motif; contains no data.
Methods Paper/Adaptive Intelligence

The Capability Transfer Ledger: Measuring Whether AI Skills Survive Model Upgrades

A methods paper on measuring capability transfer: whether AI agent skills keep working across model, tool and task changes, including negative transfer.

Evidence status: Proposal / Hypothesis

↳ methods proposal; no measurements

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "The Capability Transfer Ledger: Measuring Whether AI Skills Survive Model Upgrades". Decorative abstract motif; contains no data.
Research Proposal/Context / Skills / Transfer

Evidence-Preserving Context: Compressing Agent Memory Without Losing Obligations

A research proposal for context compaction that keeps obligations, permissions, deadlines and evidence out of lossy summaries while cutting an agent's token cost.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Evidence-Preserving Context: Compressing Agent Memory Without Losing Obligations". Decorative abstract motif; contains no data.
Research Note/Trust & Accountable AI Work

Rights as Infrastructure: Building AI Datasets That Know How They May Be Used

A research note on AI training data rights as infrastructure: purpose grants, consent, residency, expiry, revocation, descendants and training eligibility.

Evidence status: Proposal / Hypothesis

↳ architecture proposal; requires legal review; no measured results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Rights as Infrastructure: Building AI Datasets That Know How They May Be Used". Decorative abstract motif; contains no data.
Research Proposal/Data & Learning Systems

A Rights-Aware Dataset Compiler for AI Training and Evaluation

A research proposal for a rights-aware dataset compiler: dataset builds that check purpose, lineage, consent and contamination at build time and fail closed.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested; requires legal review

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "A Rights-Aware Dataset Compiler for AI Training and Evaluation". Decorative abstract motif; contains no data.
Research Note/Enterprise / Sovereign AI

Cost Per Verified Outcome: A Better Economic Unit for Agentic AI

A research note defining cost per verified outcome (CPVO) and comparing it with cost per token, request, seat and task as a unit for agentic AI economics.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Cost Per Verified Outcome: A Better Economic Unit for Agentic AI". Decorative abstract motif; contains no data.
Position Paper/Model Intelligence / Faros

Why Better Foundation Models May Make Evaluation More Valuable, Not Less

A position paper stress-testing AI evaluation against 10× better models and 10× cheaper inference, and arguing that verification and assurance gain value.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Why Better Foundation Models May Make Evaluation More Valuable, Not Less". Decorative abstract motif; contains no data.
Benchmark Design/Evaluation & Verification

Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action

A benchmark design for AI agents that take action: executable environments, state-based verification, cost reporting, permissions, recovery and reproducibility.

Evidence status: Benchmark Design

↳ benchmark design; not yet run

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action". Decorative abstract motif; contains no data.
Benchmark Design/Evaluation & Verification

VerifiedWork Recovery: Evaluating AI Agents Under Failure and Partial Effects

A benchmark design for evaluating AI agents under failure: stale state, tool errors, unknown effects, interrupted actions, partial completion and safe stopping.

Evidence status: Benchmark Design

↳ benchmark design; not yet run

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "VerifiedWork Recovery: Evaluating AI Agents Under Failure and Partial Effects". Decorative abstract motif; contains no data.
Benchmark Design/Evaluation & Verification

VerifiedWork Transfer: Measuring Capability Across Model and Tool Changes

A benchmark design measuring whether AI agent capabilities survive changes of model, provider, tool interface, task family and harness, including negative transfer.

Evidence status: Benchmark Design

↳ benchmark design; not yet run

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "VerifiedWork Transfer: Measuring Capability Across Model and Tool Changes". Decorative abstract motif; contains no data.
Benchmark Design/Evaluation & Verification

VerifiedWork Context: Measuring What AI Agents Must Remember

A benchmark design measuring what AI agents must remember: obligations, constraints, permission changes, superseded facts and revoked data, across compaction.

Evidence status: Benchmark Design

↳ benchmark design; not yet run

Oct 3, 2026 · 11 min readRead research ↗
Cover image for "VerifiedWork Context: Measuring What AI Agents Must Remember". Decorative abstract motif; contains no data.
Benchmark Design/Evaluation & Verification

VerifiedWork Control: Evaluating Delegation, Approval, Revocation, and Agent Authority

A benchmark design for AI agent authorization: delegation, approval binding, revocation latency, budgets and prompt-injection resistance, tested on system and agent.

Evidence status: Benchmark Design

↳ benchmark design; cites one published measured Ethen system card (R08)

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "VerifiedWork Control: Evaluating Delegation, Approval, Revocation, and Agent Authority". Decorative abstract motif; contains no data.
Research Protocol/Model Intelligence / Faros

How to Test Whether Learned AI Routing Beats Strong Rules

A research protocol for an LLM routing experiment: strong-rule baselines, propensity-logged data, factorial cache controls, non-inferiority tests and decision rules.

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "How to Test Whether Learned AI Routing Beats Strong Rules". Decorative abstract motif; contains no data.
Research Protocol/Evaluation & Verification

How Should We Measure the Reliability of LLM Verifiers?

A research protocol for LLM verifier reliability: stratified gold sets, false accept and reject rates, calibration, drift and exploit audits, and grader cards.

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "How Should We Measure the Reliability of LLM Verifiers?". Decorative abstract motif; contains no data.
Research Proposal/Enterprise / Sovereign AI

Ethen Synthetic Enterprise: An Executable World for Enterprise-Agent Research

A research proposal for enterprise agent simulation: an executable synthetic company with CRM, support, documents, identity, approvals, finance and email.

Evidence status: Proposal / Hypothesis

↳ research proposal; not built

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Ethen Synthetic Enterprise: An Executable World for Enterprise-Agent Research". Decorative abstract motif; contains no data.
Research Note/Trust & Accountable AI Work

Unknown Effects in Autonomous AI Systems: Why Timeouts Are Not Permission to Retry

A research note on idempotency for AI agents: unknown effects after timeouts, reconcile-before-retry, idempotency keys, compensation and exactly-once limits.

Evidence status: Research Synthesis

↳ research synthesis; no new measured Ethen results

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Unknown Effects in Autonomous AI Systems: Why Timeouts Are Not Permission to Retry". Decorative abstract motif; contains no data.
Research Paper/Data & Learning Systems

Toward a Failure Genome of Software Agents

A research paper proposing a multi-axis AI agent failure taxonomy, the failure genome, built on recent work on failure modes, attribution and critical steps.

Evidence status: Research Synthesis

↳ literature survey and taxonomy proposal; no Ethen failure dataset measured

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Toward a Failure Genome of Software Agents". Decorative abstract motif; contains no data.
Research Proposal/Enterprise / Sovereign AI

Process Memory: Learning How Organizations Actually Get Work Done

A research proposal for process memory for AI agents: mining completed, verified work into per-organization process models that guide plans and flag anomalies.

Evidence status: Proposal / Hypothesis

↳ research proposal; untested

Oct 3, 2026 · 11 min readRead research ↗
Cover image for "Process Memory: Learning How Organizations Actually Get Work Done". Decorative abstract motif; contains no data.
Research Proposal/Enterprise / Sovereign AI

Tenant Replay: Private Evaluation Inside Enterprise Boundaries

A research proposal for private AI evaluation: replaying an enterprise's own historical agent tasks inside its boundary, with only bounded aggregates leaving.

Evidence status: Proposal / Hypothesis

↳ research proposal; not built; requires security and legal review

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "Tenant Replay: Private Evaluation Inside Enterprise Boundaries". Decorative abstract motif; contains no data.
Research Protocol/Model Intelligence / Faros

A Research Protocol for Model Change Assurance

A research protocol testing whether model change assurance predicts live outcomes: paired replay, regression certificates, randomized rollout and false reassurance.

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run; no model change assurance results exist

Oct 3, 2026 · 14 min readRead research ↗
Cover image for "A Research Protocol for Model Change Assurance". Decorative abstract motif; contains no data.
Research Note/Model Intelligence / Faros

Why AI Routers Should Log Propensities From Day One

Why AI routers need propensity logging from the first decision: candidate sets, selection probabilities and verified outcomes make off-policy evaluation possible.

Evidence status: Research Synthesis

↳ technical research note; external literature and Ethen design decisions; no Ethen measurements

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "Why AI Routers Should Log Propensities From Day One". Decorative abstract motif; contains no data.
Research Protocol/Context / Skills / Transfer

How to Measure Whether AI Skills Survive a Frontier-Model Upgrade

A research protocol for AI skill portability: a pre-registered event study of whether agent skills transfer, degrade or reverse after a frontier-model upgrade.

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run; no skill-survival measurements exist

Oct 3, 2026 · 12 min readRead research ↗
Cover image for "How to Measure Whether AI Skills Survive a Frontier-Model Upgrade". Decorative abstract motif; contains no data.
Research Protocol/Context / Skills / Transfer

How Should We Measure How Much Context an AI Agent Actually Needs?

A research protocol for the AI agent context budget: dose-response curves for five context strategies, with obligation retention and revoked-data exposure.

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run; no measured context-budget curves exist

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "How Should We Measure How Much Context an AI Agent Actually Needs?". Decorative abstract motif; contains no data.
Research Protocol/Context / Skills / Transfer

Testing Whether Recovery Knowledge Transfers Across Tools

A research protocol for recovery transfer: does agent recovery knowledge carry to unseen APIs, tool versions and failure mechanisms, including when to stop?

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run; no recovery-transfer evidence exists

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "Testing Whether Recovery Knowledge Transfers Across Tools". Decorative abstract motif; contains no data.
Research Protocol/Adaptive Intelligence

How to Test Whether Verified Experience Improves AI Agents

A research protocol on learning from experience for AI agents: do verified, failure-rich data beat raw traces at matched volume, on held-out work?

Evidence status: Protocol / Planned Experiment

↳ research protocol; not yet run; no measured gain curves exist

Oct 3, 2026 · 14 min readRead research ↗
Cover image for "How to Test Whether Verified Experience Improves AI Agents". Decorative abstract motif; contains no data.
Research Proposal/Enterprise / Sovereign AI

Private AI Improvement Without Raw Data Export

Private AI improvement without raw data export: tenant-local learning, federated evaluation, secure aggregation and differential privacy, each with its threat model.

Evidence status: Proposal / Hypothesis

↳ research survey and proposal; no Ethen implementation or measurement; requires privacy, security and legal review

Oct 3, 2026 · 13 min readRead research ↗
Cover image for "Private AI Improvement Without Raw Data Export". Decorative abstract motif; contains no data.
Research Proposal/Enterprise / Sovereign AI

Toward a Sovereign Improvement Protocol for Enterprise AI

A research proposal for sovereign AI: how enterprise AI could improve across private deployments without raw data leaving the customer boundary.

Evidence status: Proposal / Hypothesis

↳ frontier research proposal; not built; not production-ready; requires privacy, security and legal review

Oct 3, 2026 · 15 min readRead research ↗
Cover image for "Toward a Sovereign Improvement Protocol for Enterprise AI". Decorative abstract motif; contains no data.
System Card/AI Security

AgentTrustBench system card: autonomy boundaries on one pinned build

System card for one offline enumeration of a pinned Ethen build: 197 conditions, 194 passed. Not a paper and not a security disclosure.

Evidence status: System Evidence

↳ Offline enumeration · one pinned build
Sep 22, 2026Read research ↗
Diagram of an agent action passing through an approval boundary to a recorded result.

One system

Research, intelligence and product compound together.

The loop runs in every direction. Product use raises research questions, evaluations reopen old answers, and some research ends in knowledge that never becomes a product.

ResearchIntelligenceProductEvidence
  1. Discovers and validatesYou are here

    Ethen Research Lab

    The research organization studying intelligence, computing and science, with an explicit evidence status on everything it publishes.

  2. Turns research into intelligence

    Faros

    Ethen's model and intelligence-development program: evaluation, routing, data and adaptation, building toward increasingly proprietary capability.

    Explore Faros →
  3. Puts intelligence to work

    Ethen

    The product people use to think, research, write and build with AI.
    Explore Ethen →
  4. Closes the loop

    Evidence

    Outcomes, failures and evaluations become the questions the next round of research starts from.
A record you can examine

Each publication states its methods, evidence, and limitations. System cards describe a specific system and build; they do not imply peer review or broader benchmark performance.

Ethen

Products

  • Ethen
  • Research
  • Code
  • Local Models
  • Computer
  • Sentinel
  • Studio
  • Flow
  • Designer
  • Founder
  • Gateway
  • Model Intelligence
  • Compute
  • iBot
  • Voice

Platform

  • Platform
  • Orchestration
  • Connectors
  • Evidence
  • Approvals
  • Status

Models

  • Faros
  • Flagship Model Library
  • Model Intelligence
  • Open Source Model Library
  • Local Models
  • Media Model Library

Solutions

  • Coding
  • Security Teams
  • Enterprise

Legal

  • Legal & Trust Center
  • Privacy
  • Terms
  • Acceptable Use
  • Cookies

Resources

  • Research Lab
  • Blog
  • Docs
  • API Reference
  • Guides
  • Changelog

Company

  • Company
  • Contact
  • Careers
Intelligence for what comes next.© 2027 UpCube Technologies Inc. All rights reserved.