Publications
Browse by type and status. Every publication carries a classification and an evidence status, so a proposal is never read as a result.
These are publications of the UpCube Research Lab, UpCube’s research organisation. They are separate from the Ethen Research workspace, a product in development, and from the Blog, which carries company and product updates.
The archive
Published items, by classification
41
- Synthesis13 of 41
- Design3 of 41
- Proposal12 of 41
- Protocol7 of 41
- Benchmark method5 of 41
- Measured result1 of 41
Generated from the publication catalogue. Select a classification to filter the archive.
01Featured
Featured
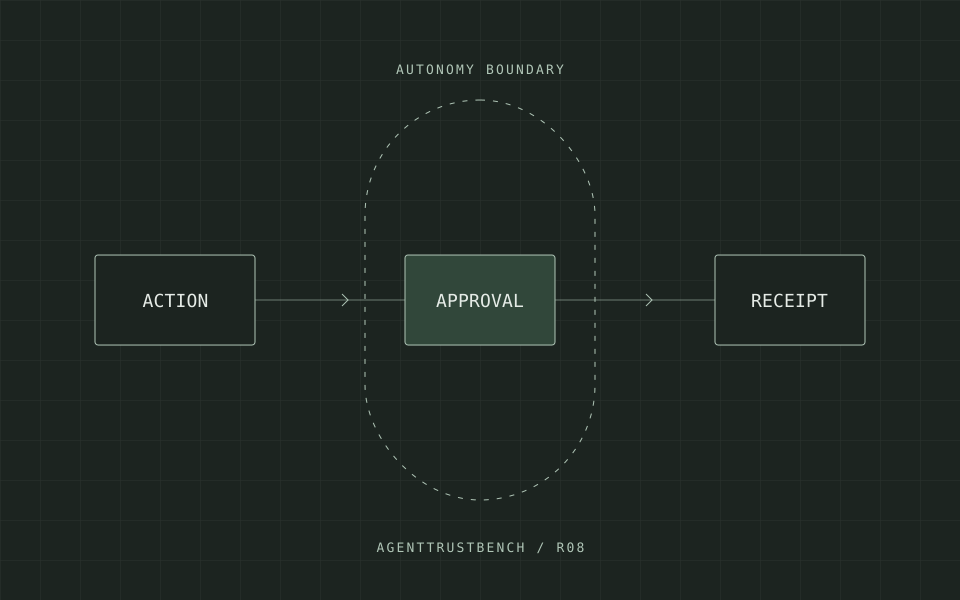
System Card
AgentTrustBench system card: autonomy boundaries on one pinned build
System card for one offline enumeration of a pinned Ethen build: 197 conditions, 194 passed. Not a paper and not a security disclosure.
- Classification
- Classification: Measured resultReports a measurement UpCube ran, only within the scope the publication states.
- Evidence status
- System Evidence
- Offline enumeration · one pinned build
Also featured
- Classification: Synthesis
Verified Adaptive Intelligence: Learning From Work That Can Be Proven
Position Paper15 min read
- Classification: Synthesis
From AI Traces to Verified Experience
Research Note12 min read
- Classification: Benchmark method
Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action
Benchmark Design12 min read
- Classification: Protocol
How to Test Whether Verified Experience Improves AI Agents
Research Protocol14 min read
- Classification: Proposal
Toward a Sovereign Improvement Protocol for Enterprise AI
Research Proposal15 min read
02Archive
All publications
The complete published archive.
Position Paper15 min read
Verified Adaptive Intelligence: Learning From Work That Can Be Proven
A research agenda for AI agents that learn only from experience that is verified, rights-cleared and shown to transfer across tasks, tools and model generations.
Classification: SynthesisEvidence status: Research Synthesis
Research Note12 min read
From AI Traces to Verified Experience
Logs, traces, trajectories, outcomes and corrections are not the same asset. A research note on what turns agent telemetry into verified experience.
Classification: SynthesisEvidence status: Research Synthesis
Technical Report13 min read
Work Receipts: A Verifiable Record for Autonomous AI Work
A technical report proposing the Work Receipt: one signed record of authority, actions, effects, verification, cost and rights for every unit of autonomous AI work.
Classification: DesignEvidence status: Proposal / Hypothesis
Research Note12 min read
Mandates: Compiling Human Intent Into Bounded Agent Authority
A research note on mandates: one object that compiles human intent into AI agent authorization, budgets, approvals, delegation limits, expiry and revocation.
Classification: DesignEvidence status: Proposal / Hypothesis
Research Proposal13 min read
Commitment Graphs: Why AI Agents Need to Know What Is Still Unfinished
A research proposal for commitment graphs: tracking intent, obligations, preconditions, effects and evidence so AI agents stop declaring unfinished work complete.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Proposal12 min read
Recovery Atlas: Teaching AI Agents When to Retry, Reconcile, Escalate, or Stop
A research proposal on AI agent error recovery: branch each failure in a sandbox into candidate recoveries and learn when to retry, reconcile, escalate or stop.
Classification: ProposalEvidence status: Proposal / Hypothesis
Methods Paper12 min read
Evaluating the Evaluators: Reward Integrity for AI Agents
A methods paper on reward integrity for AI agents: verifier false accepts and rejects, abstention, grader drift, expert disagreement and reward hacking.
Classification: SynthesisEvidence status: Research Synthesis
Position Paper12 min read
Faros: Researching How Intelligence Should Choose Intelligence
A position paper reframing AI model routing as an execution-configuration decision across model, context, tools, verification, recovery, cost and risk.
Classification: SynthesisEvidence status: Research Synthesis
Survey12 min read
Why Learned AI Model Routing Must Beat Good Rules
A survey of learned LLM routing: what RouteLLM, RouterBench and LLMRouterBench show, why strong rules are the right baseline, and how to test non-inferiority.
Classification: SynthesisEvidence status: Research Synthesis
Research Proposal12 min read
Counterfactual Replay for AI Agents
A research proposal for counterfactual evaluation of AI agents: replaying completed tasks under alternative models, tools, context and recovery strategies.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Note12 min read
Model Change Assurance: Testing AI Upgrades Before They Reach Real Work
A research note on model change assurance: replaying an organization's own historical tasks to find regressions before an LLM upgrade reaches real work.
Classification: SynthesisEvidence status: Research Synthesis
Position Paper13 min read
What Makes AI Data Defensible?
A position paper on the AI data moat: why volume is not defensibility, and eight axes, from rights to outcome density and transfer, that decide what compounds.
Classification: SynthesisEvidence status: Research Synthesis
Research Note12 min read
The Outcome Warehouse: Turning Completed AI Work Into Research Assets
A research note on the Outcome Warehouse: storing verified, versioned AI outcome data with corrections, cost, lineage, rights and delayed business results.
Classification: SynthesisEvidence status: Research Synthesis
Research Proposal13 min read
Skill IR: Toward Model-Independent Agent Capabilities
A research proposal for Skill IR: AI agent skills as portable, testable capability contracts with permissions, verifiers and compatibility records.
Classification: ProposalEvidence status: Proposal / Hypothesis
Methods Paper12 min read
The Capability Transfer Ledger: Measuring Whether AI Skills Survive Model Upgrades
A methods paper on measuring capability transfer: whether AI agent skills keep working across model, tool and task changes, including negative transfer.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Proposal12 min read
Evidence-Preserving Context: Compressing Agent Memory Without Losing Obligations
A research proposal for context compaction that keeps obligations, permissions, deadlines and evidence out of lossy summaries while cutting an agent's token cost.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Note12 min read
Rights as Infrastructure: Building AI Datasets That Know How They May Be Used
A research note on AI training data rights as infrastructure: purpose grants, consent, residency, expiry, revocation, descendants and training eligibility.
Classification: DesignEvidence status: Proposal / Hypothesis
Research Proposal12 min read
A Rights-Aware Dataset Compiler for AI Training and Evaluation
A research proposal for a rights-aware dataset compiler: dataset builds that check purpose, lineage, consent and contamination at build time and fail closed.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Note12 min read
Cost Per Verified Outcome: A Better Economic Unit for Agentic AI
A research note defining cost per verified outcome (CPVO) and comparing it with cost per token, request, seat and task as a unit for agentic AI economics.
Classification: SynthesisEvidence status: Research Synthesis
Position Paper12 min read
Why Better Foundation Models May Make Evaluation More Valuable, Not Less
A position paper stress-testing AI evaluation against 10× better models and 10× cheaper inference, and arguing that verification and assurance gain value.
Classification: SynthesisEvidence status: Research Synthesis
Benchmark Design12 min read
Ethen VerifiedWork: A Benchmark Framework for AI Systems That Take Action
A benchmark design for AI agents that take action: executable environments, state-based verification, cost reporting, permissions, recovery and reproducibility.
Classification: Benchmark methodEvidence status: Benchmark Design
Benchmark Design12 min read
VerifiedWork Recovery: Evaluating AI Agents Under Failure and Partial Effects
A benchmark design for evaluating AI agents under failure: stale state, tool errors, unknown effects, interrupted actions, partial completion and safe stopping.
Classification: Benchmark methodEvidence status: Benchmark Design
Benchmark Design12 min read
VerifiedWork Transfer: Measuring Capability Across Model and Tool Changes
A benchmark design measuring whether AI agent capabilities survive changes of model, provider, tool interface, task family and harness, including negative transfer.
Classification: Benchmark methodEvidence status: Benchmark Design
Benchmark Design11 min read
VerifiedWork Context: Measuring What AI Agents Must Remember
A benchmark design measuring what AI agents must remember: obligations, constraints, permission changes, superseded facts and revoked data, across compaction.
Classification: Benchmark methodEvidence status: Benchmark Design
Benchmark Design12 min read
VerifiedWork Control: Evaluating Delegation, Approval, Revocation, and Agent Authority
A benchmark design for AI agent authorization: delegation, approval binding, revocation latency, budgets and prompt-injection resistance, tested on system and agent.
Classification: Benchmark methodEvidence status: Benchmark Design
Research Protocol12 min read
How to Test Whether Learned AI Routing Beats Strong Rules
A research protocol for an LLM routing experiment: strong-rule baselines, propensity-logged data, factorial cache controls, non-inferiority tests and decision rules.
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Protocol12 min read
How Should We Measure the Reliability of LLM Verifiers?
A research protocol for LLM verifier reliability: stratified gold sets, false accept and reject rates, calibration, drift and exploit audits, and grader cards.
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Proposal12 min read
Ethen Synthetic Enterprise: An Executable World for Enterprise-Agent Research
A research proposal for enterprise agent simulation: an executable synthetic company with CRM, support, documents, identity, approvals, finance and email.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Note12 min read
Unknown Effects in Autonomous AI Systems: Why Timeouts Are Not Permission to Retry
A research note on idempotency for AI agents: unknown effects after timeouts, reconcile-before-retry, idempotency keys, compensation and exactly-once limits.
Classification: SynthesisEvidence status: Research Synthesis
Research Paper12 min read
Toward a Failure Genome of Software Agents
A research paper proposing a multi-axis AI agent failure taxonomy, the failure genome, built on recent work on failure modes, attribution and critical steps.
Classification: SynthesisEvidence status: Research Synthesis
Research Proposal11 min read
Process Memory: Learning How Organizations Actually Get Work Done
A research proposal for process memory for AI agents: mining completed, verified work into per-organization process models that guide plans and flag anomalies.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Proposal13 min read
Tenant Replay: Private Evaluation Inside Enterprise Boundaries
A research proposal for private AI evaluation: replaying an enterprise's own historical agent tasks inside its boundary, with only bounded aggregates leaving.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Protocol14 min read
A Research Protocol for Model Change Assurance
A research protocol testing whether model change assurance predicts live outcomes: paired replay, regression certificates, randomized rollout and false reassurance.
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Note12 min read
Why AI Routers Should Log Propensities From Day One
Why AI routers need propensity logging from the first decision: candidate sets, selection probabilities and verified outcomes make off-policy evaluation possible.
Classification: SynthesisEvidence status: Research Synthesis
Research Protocol12 min read
How to Measure Whether AI Skills Survive a Frontier-Model Upgrade
A research protocol for AI skill portability: a pre-registered event study of whether agent skills transfer, degrade or reverse after a frontier-model upgrade.
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Protocol13 min read
How Should We Measure How Much Context an AI Agent Actually Needs?
A research protocol for the AI agent context budget: dose-response curves for five context strategies, with obligation retention and revoked-data exposure.
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Protocol13 min read
Testing Whether Recovery Knowledge Transfers Across Tools
A research protocol for recovery transfer: does agent recovery knowledge carry to unseen APIs, tool versions and failure mechanisms, including when to stop?
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Protocol14 min read
How to Test Whether Verified Experience Improves AI Agents
A research protocol on learning from experience for AI agents: do verified, failure-rich data beat raw traces at matched volume, on held-out work?
Classification: ProtocolEvidence status: Protocol / Planned Experiment
Research Proposal13 min read
Private AI Improvement Without Raw Data Export
Private AI improvement without raw data export: tenant-local learning, federated evaluation, secure aggregation and differential privacy, each with its threat model.
Classification: ProposalEvidence status: Proposal / Hypothesis
Research Proposal15 min read
Toward a Sovereign Improvement Protocol for Enterprise AI
A research proposal for sovereign AI: how enterprise AI could improve across private deployments without raw data leaving the customer boundary.
Classification: ProposalEvidence status: Proposal / Hypothesis
System Card
AgentTrustBench system card: autonomy boundaries on one pinned build
System card for one offline enumeration of a pinned Ethen build: 197 conditions, 194 passed. Not a paper and not a security disclosure.
Classification: Measured resultEvidence status: System Evidence
03Taxonomy
What the classifications mean
The classification says what kind of work a publication is. It is derived from each publication’s own evidence note. Only a measured result reports a measurement, and only within its stated scope.
- Synthesis
- Analysis of existing evidence and literature. It reports no new UpCube measurements.
- 13
- Design
- An architecture or system design. It describes how something could work; it reports no measurements.
- 3
- Proposal
- A proposed direction or hypothesis that has not been tested.
- 12
- Protocol
- A defined method for an experiment that has not been run, so it reports no results.
- 7
- Benchmark method
- A benchmark specification. It has not necessarily been run, and it implies no scores.
- 5
- Measured result
- Reports a measurement UpCube ran, only within the scope the publication states.
- 1
04Evidence
Evidence status
Every publication declares how strong its evidence is. Format and evidence status are separate: a benchmark design is a specification, not a benchmark result.
- Measured / Empirical
- Ethen ran an experiment, benchmark, or measurement and reports the result.
- 0
- System Evidence
- Evidence tied to a specific implemented or pinned Ethen system or build. It does not generalize beyond that build.
- 1
- Research Synthesis
- Analysis of existing evidence and literature. No new Ethen measurements are implied.
- 13
- Protocol / Planned Experiment
- The method is defined. The experiment has not been run, so no results are reported.
- 7
- Benchmark Design
- A benchmark specification. It has not necessarily been run, and no scores are implied.
- 5
- Proposal / Hypothesis
- A proposed direction, system, or hypothesis that remains untested.
- 15